Supermemory vs Pinecone: Which is Better?
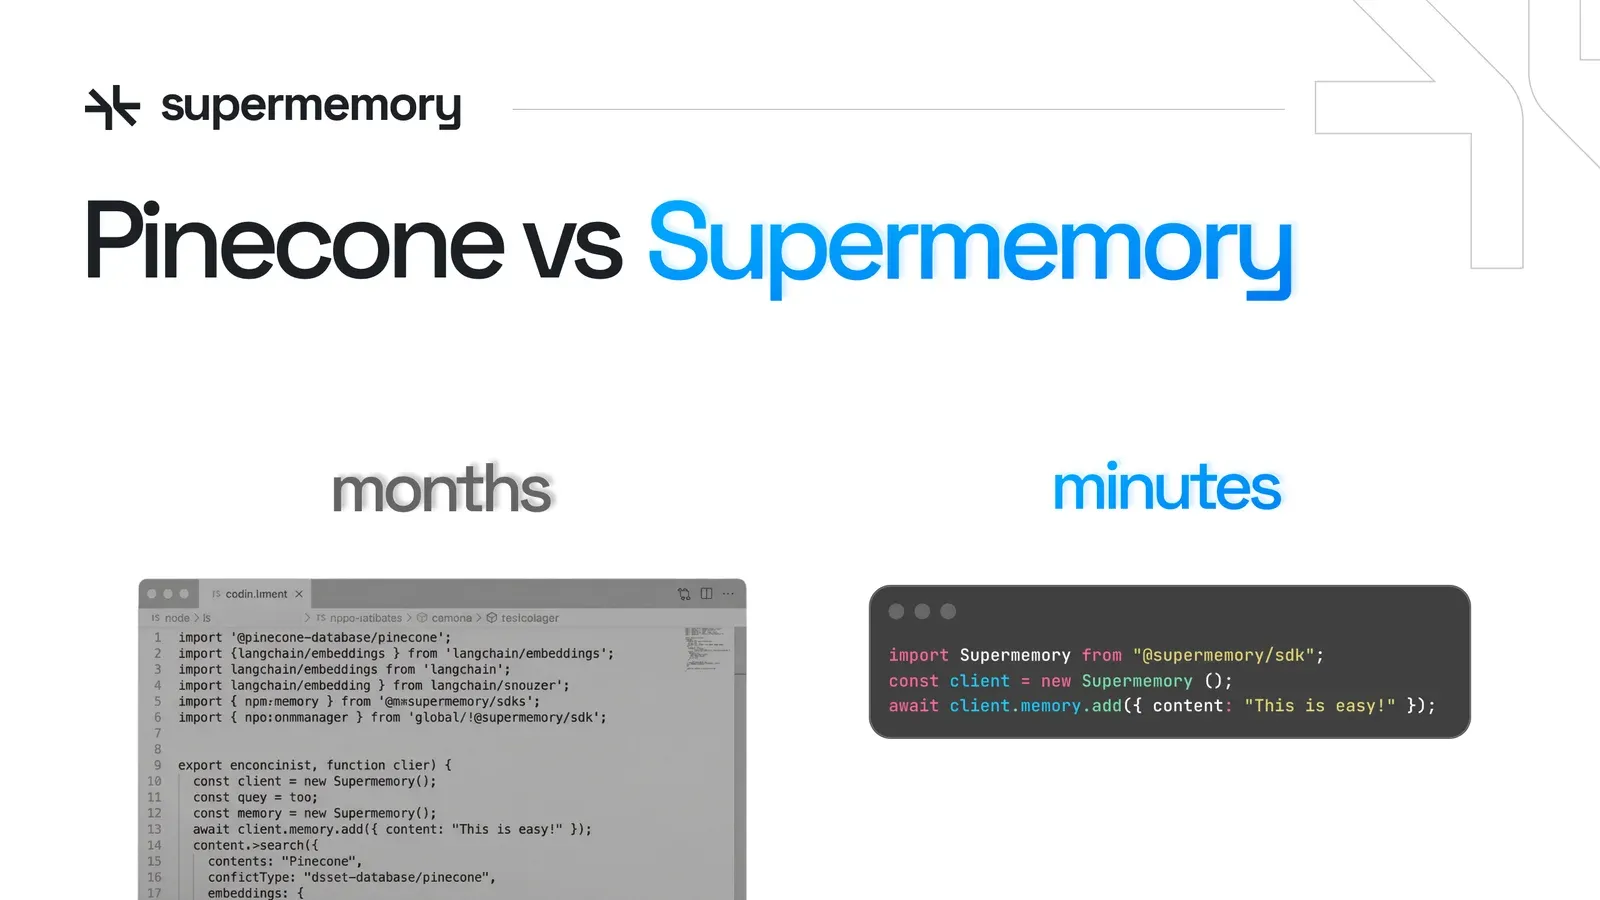
You picked Pinecone because it handled vector search at scale, and that part works exactly as advertised. But building memory for an AI agent that actually feels intelligent means you're also building an embedding pipeline, extraction logic, chunking strategies, reranking layers, and custom code to track user context across sessions. Most teams spend weeks just deciding which embedding model to use before writing a single line of product logic. The real Pinecone comparison isn't about milliseconds per query or how many vectors you can index. It's about whether you want to spend months wiring together infrastructure or five minutes integrating an API that ships with all of it already solved.
TLDR:
- Pinecone handles vector search but leaves embedding, extraction, chunking, and memory logic to you
- Supermemory delivers sub-300ms end-to-end recall with memory graphs, user profiles, and connectors built in
- Building memory with Pinecone typically requires 5-7 vendor relationships across months of engineering work
- Supermemory ranks #1 on LongMemEval (85.4%), LoCoMo, and ConvoMem benchmarks for temporal reasoning and context quality
- Supermemory provides a complete memory API for AI agents with state-of-the-art retrieval, RAG, user profiles, connectors, and extractors in one system
What is Pinecone?
Pinecone is a vector database. It stores embeddings and runs approximate nearest neighbor (ANN) search at scale, but lacks long-term memory capabilities for LLMs. That's the core of what it does, and it does that part well.
The problem is what it doesn't do. Pinecone gives you a place to put vectors and query them by similarity. Everything else, the embedding models, extraction pipelines, chunking logic, memory extraction, reranking, user context, you build yourself. It's a low-level LLM infrastructure component, not a complete memory solution.
For teams building RAG pipelines or semantic search, Pinecone became a go-to choice because it abstracted away the complexity of managing vector indexes at scale. But as AI agents grew more sophisticated, that abstraction started showing gaps. Knowing that two chunks of text are semantically similar is not the same as remembering what a user told you three sessions ago, or understanding how a new fact contradicts something stored six months back.
Pinecone is infrastructure. It has no concept of users, no temporal reasoning, no relationship tracking between memories. You query it, it returns nearest vectors, and you figure out the rest. For some use cases that's fine. For building agents that actually feel intelligent, it puts the full burden back on your team.
What is Supermemory?
Supermemory was built to solve the exact problem Pinecone leaves behind. Where Pinecone gives you a vector index, we give you a complete memory API. One system. No assembly required.
At the core is a proprietary vector graph engine that tracks relationships between memories, and goes way beyond similarity scores. Pair that with built-in document extractors, user profiles, connectors to Notion, Slack, Gmail, Google Drive, and a hybrid retrieval layer with context-aware reranking, and you have something fundamentally different from a vector database.
The numbers back it up. We process 100B+ tokens monthly with sub-300ms recall times. On LongMemEval, LoCoMo, and ConvoMem benchmarks, we rank #1 across the board, with LoCoMo showing 59.7% P@1 (vs 34.4% for major competitors), 83.5% Recall@10, and 71.1% NDCG@10.
The design philosophy matters here. Memory shouldn't be fragile, expensive, or rebuilt from scratch by every dev team. So we made it a single API call. User profiles get built automatically from behavior. The memory graph evolves in real time. Temporal reasoning, contradiction handling, knowledge updates, all handled for you.
Vector Database vs Memory System: Understanding the Core Difference
A vector database is a fast lookup table for embeddings. It answers one question: "What's similar to this?" A memory system answers something harder: "What does this agent need to know right now, given who this user is and what's happened before?"
That gap is not minor. To close it with Pinecone, your team typically wires together 5 to 7 separate services: an embedding model, an extraction tool like FireCrawl or Reducto, a chunking layer, a reranker, a graph store for relationships, and custom glue code. That's months of engineering before you've written a single line of product logic.
"Vector databases are evolving beyond pure ANN search, but the retrieval problem was never the hard part. Relationship tracking, temporal context, and user-aware memory still require layers that no vector DB ships out of the box." trends in vector database architectures, 2026
The graph engine in Supermemory tracks how memories relate to each other, flags contradictions, handles updates, and reasons about time. If a user told your agent something in January and corrected it in March, a vector database returns both chunks with similar scores. Supermemory knows which one is current.
Pinecone gives you retrieval. We give you memory with context assembly baked in. One requires a team. The other requires an API key.
Setup Complexity and Time to Production
Building memory with Pinecone means you're also building an embedding pipeline, a chunking strategy, extraction logic, a reranker, and custom consolidation code. That stack easily crosses thousands of lines before your first production query. Most teams spend weeks just deciding which embedding model to use.
Supermemory ships with all of that already solved. Connectors for Notion, Slack, Google Drive, S3, and Gmail are built in. Multi-modal extractors handle PDFs, images, audio, and video without extra configuration. The TypeScript SDK, Python SDK, and REST API are all available on day one.
Getting started looks like this:
import Supermemory from "@supermemory/sdk";
const client = new Supermemory();
await client.memory.add({ content: "User prefers TypeScript over Python" });
const results = await client.memory.search({ query: "language preferences" });
No embedding model decision. No extraction pipeline. No reranking config. Five minutes to production, not five months.
The compounding cost of the Pinecone route is also worth naming. Every new data source requires a new extraction adapter. Every new modality reopens the architecture question. Adding a Gmail connector with Supermemory is a config change, not a sprint.
Memory Intelligence and Context Quality
Pinecone returns vectors ranked by similarity. It has no awareness of time, no concept of contradiction, and no understanding of who the user is. Handling long-context scenarios is the real infrastructure challenge now, and similarity scores alone don't cut it.
Supermemory's memory graph tracks ontology-aware edges between memories. When a fact changes, the graph updates. When two stored facts conflict, the system resolves it. Temporal reasoning is built in, not bolted on.
User profiles get built automatically: static facts the agent should always know, plus evolving episodic memory from recent conversations. No manual configuration required.
The LongMemEval-S benchmark shows what that architecture produces:
Task
Supermemory
Others
Overall
85.4%
N/A
Single-Session User
92.3%
71.0%
Knowledge Update
89.7%
77.5%
Temporal Reasoning
82.0%
62.4%
Multi-Session
76.7%
57.9%
Pinecone scores none of those dimensions. It was never designed to.
Performance, Scale, and Cost Comparison
Pinecone advertises 20-100ms search latency on billion-vector datasets. That number sounds fast until you remember it excludes embedding generation, extraction, reranking, and any consolidation logic your team wrote. Real end-to-end latency with a Pinecone stack routinely runs much higher. Supermemory delivers sub-300ms end-to-end, fully assembled, including retrieval and context assembly.
The cost picture is where the gap becomes hard to ignore. A Pinecone-based memory stack typically spans 5-7 vendor relationships: the vector DB itself, an embedding API, an extraction service like FireCrawl or Reducto, a reranker, and custom infrastructure glue. Each line item has its own billing cycle and failure mode.
Supermemory runs on one bill: starting at free for 1M tokens and 10K searches, $19/month for 3M tokens and 100K searches (Pro tier), $399/month for 80M tokens and 20M searches (Scale tier), or custom enterprise pricing for unlimited usage.
Intelligent context assembly also cuts token usage down compared to naive retrieval, so you spend less on LLM calls too. SOC 2 Type 2, HIPAA, and GDPR compliance come included as well. No separate audit. No compliance vendor. One subscription covers everything.
Why Supermemory is the Better Choice
Pinecone serves teams that need raw vector search and have the bandwidth to build everything else themselves. If you want full control over every layer and have months to wire it together, that path exists.
For most startup engineering teams, that tradeoff doesn't make sense. Here's why Supermemory wins:
- The complete context stack ships in one API: memory graph, user profiles, extractors, connectors, hybrid retrieval. What takes 3-6 months to assemble with Pinecone takes an afternoon.
- Benchmark quality isn't close. Supermemory ranks #1 on LongMemEval (85.4%), LoCoMo, and ConvoMem. These measure what agents actually need: temporal reasoning, knowledge updates, multi-session recall. Pinecone wasn't designed for any of them.
- Total cost of ownership runs 2-3x lower by collapsing 5-7 vendor relationships into one bill, while keeping end-to-end latency under 300ms.
Already running Pinecone? You don't have to rip it out. Keep your existing vector store and layer Supermemory's memory intelligence on top. A few lines of code is all it takes to get user profiles, relationship tracking, and real context assembly running against your current setup.
The question isn't really Pinecone vs Supermemory. It's whether you want to spend the next quarter building memory infrastructure or shipping product.
Final Thoughts on LLM Memory Architecture
The gap between vector databases and memory systems isn't technical preference, it's architectural philosophy. One gives you fast lookups and leaves context assembly to your team. The other ships with user profiles, temporal reasoning, and relationship tracking built in because that's what agents actually need to feel intelligent. If you're building memory from scratch right now, try Supermemory and see what happens when the infrastructure just works without six vendor integrations and custom glue code.
FAQ
How should I decide between Supermemory and Pinecone for my agent application?
If your team wants raw vector search and has 3-6 months to wire together embedding models, extractors, chunking logic, and reranking yourself, Pinecone is that foundation. If you need production memory intelligence in an afternoon (with user profiles, temporal reasoning, and relationship tracking already built), Supermemory is the only real option. The question comes down to whether you're building infrastructure or shipping product.
What's the actual difference between a vector database and a memory system?
A vector database returns semantically similar chunks based on embeddings. A memory system tracks relationships between facts, handles contradictions, reasons about time, and builds user context automatically. Pinecone answers "what's similar to this?" Supermemory answers "what does this agent need to know right now, given who this user is and what happened before?" That gap requires 5-7 separate services to bridge with Pinecone, or one API call with Supermemory.
When does it make sense to use Pinecone over Supermemory?
Pinecone makes sense if you have a dedicated infrastructure team, months of runway, and need complete control over every layer of your context stack. Most startup engineering teams don't fit that profile. If your goal is agent intelligence over database engineering, or if you're measuring time-to-production in weeks instead of quarters, Supermemory will get you there faster at lower total cost.
Can I migrate from Pinecone without rebuilding everything?
Yes. You can keep your existing Pinecone vector store and layer Supermemory's memory intelligence on top of it. A few lines of code gets you user profiles, relationship tracking, and real context assembly running against your current setup. You don't have to rip out infrastructure to start shipping better agent experiences. Migration can be incremental instead of a full rewrite.
What happens to my memory stack costs when I switch from Pinecone?
With Pinecone, you're typically managing 5-7 vendor relationships: the vector DB, embedding API, extraction service like FireCrawl or Reducto, reranker, and custom infrastructure glue. Each has separate billing and failure modes. Supermemory collapses that into one subscription starting at $19/month for 3M tokens and 100K searches, with intelligent context assembly that also cuts your downstream LLM token costs. Total cost of ownership runs 2-3x lower in most production scenarios.