LLM context window: how to increase it and work past the limit
You can't increase a hosted model's context window: the provider sets it, and current models from Anthropic, OpenAI and Google top out at about 1 million tokens. What you can do is switch to a model with a bigger window, raise the limit a local model runs with, extend an open model with fine-tuning, or fit more work into the window you have with compression, compaction, retrieval and memory.
This guide covers each option, with window sizes checked against the providers' docs on October 16, 2026, and explains why a bigger window doesn't fix everything.
What is an LLM context window?
An LLM's context window is the maximum number of tokens it can work with in one request: your input, the tokens it generates and, on reasoning models, its reasoning tokens (OpenAI). Anthropic's docs describe it as a "working memory" for the model, separate from the data it was trained on (Anthropic).
Everything in the request counts: the system prompt, the conversation so far, tool definitions and tool results, documents, images and the answer itself. A token is a piece of a word. On Claude's current tokenizer, 1M tokens is roughly 555,000 English words (Anthropic).
The window also resets on every request. Anthropic's Messages API is stateless, so a long conversation only fits because your app sends the whole history again each turn. That's why long chats eventually hit the limit.
How big are LLM context windows in 2026?
These are the current models' limits as published on October 16, 2026. Providers change them often, so check the linked page before you depend on a number.
| Model | Context window | Max output | Source |
|---|---|---|---|
| Claude Opus 5.5 (same for Fable 5.1, Sonnet 5.5 and Haiku 5.5) | 1M tokens | 128K tokens | Anthropic |
| GPT-6 Astra (same for GPT-6.1 Sol and GPT-6 Luna) | 1,050,000 tokens, shared by input and output | 128,000 tokens | OpenAI |
| Gemini 4 Argon | 1,048,576 tokens, shared by input and output | 65,536 by default, up to 1,048,576 with long decode | |
| Gemini 3.8 Flash | 1,048,576 input tokens | 65,536 tokens | |
| gpt-oss-120b (open weight) | 131,072 tokens | 131,072 tokens | OpenAI |
Some older models are smaller, like Claude Sonnet 4.5 at 200K tokens (Anthropic).
Long prompts can also cost more per token. On GPT-6 Astra, prompts over 272K input tokens are billed at twice the input rate and 1.5 times the output rate for the whole request (OpenAI), and on Claude Haiku 5.5, prompts over 100,000 tokens cost more (Anthropic).
How to increase the context window of an LLM
There are five options, from least work to most.
1. Use a model with a bigger window
On a hosted model, switching is the only way to get a bigger native window. Check the model's own page, because windows differ between models from the same provider.
2. Raise the limit on a local model
Local runtimes often run a model with less context than it supports, to save memory. Ollama picks its default from your GPU memory: 4K tokens under 24 GiB of VRAM, 32K from 24 to 48 GiB, and 256K at 48 GiB or more (Ollama docs). You can raise it in the app's settings, or when you start the server:
OLLAMA_CONTEXT_LENGTH=64000 ollama serveA longer context needs more memory, and you can't go past the model's own maximum. Run ollama ps to see the context length a loaded model actually got.
3. Extend an open model with fine-tuning
If you control the weights, you can stretch the window of models that use rotary position embeddings (RoPE). Position Interpolation extended LLaMA models to 32,768 tokens within 1,000 fine-tuning steps (Chen et al., 2023). YaRN reports doing it with 10x fewer tokens and 2.5x fewer training steps than earlier methods (Peng et al., 2023). Neither works on a hosted API.
4. Compress the input
Semantic compression shrinks a long document before the model reads it. Its authors report that models could handle texts 6 to 8 times longer than their window, with no fine-tuning (Fei et al., 2023). The method is step by step below.
5. Manage the window as you go
For conversations and agents that keep growing, compact old turns, retrieve only what the next step needs, and move whatever should outlast the session into memory. The rest of this guide covers each.
Why a bigger context window isn't always better
Fitting more text in the window doesn't mean the model uses all of it well.
- Context rot. As the token count grows, accuracy and recall degrade. Anthropic calls this context rot (Anthropic).
- Lost in the middle. Models use information at the start or end of a long input more reliably than information in the middle (Liu et al., 2023).
- Claimed length isn't usable length. In the RULER benchmark, almost every model lost accuracy as inputs got longer, and only half of the models that claimed 32K tokens or more did well at 32K (Hsieh et al., 2024).
- Length hurts on its own. Even when models could retrieve every relevant fact perfectly, their scores dropped by 13.9% to 85% as inputs got longer (Du et al., 2025).
Google's long-context guide adds two practical notes: accuracy falls when the model has to find several pieces of information instead of one, and models usually do better when the question comes after the long context (Google).
The working rule is to send the smallest set of tokens that answers the next step. Anthropic's engineering team calls it finding "the smallest set of high-signal tokens" (Anthropic, Sep 2025). That's the core of context engineering.
Compaction: keeping a long conversation inside the window
Compaction replaces older turns with a summary so the conversation can continue. Claude's API can do it on the server (Anthropic). OpenAI's Responses API compacts automatically once the conversation crosses a token threshold you set (OpenAI). Coding agents do it too: Claude Code replaces the conversation with a structured summary when it compacts (Claude Code docs). What happens when an agent hits the limit mid-task is covered in what happens when an AI agent runs out of context.
Trimming or summarizing?
There are two basic strategies. OpenAI's cookbook on session memory compares them (OpenAI, Sep 2025):
| Trimming (keep the last N turns) | Summarizing (replace older turns with a summary) | |
|---|---|---|
| Cost and speed | Cheapest, no extra model calls | Extra model work each time the summary refreshes |
| Long-range recall | Weak: older turns are simply gone | Strong: decisions and constraints carry forward |
| Main risk | Losing context | Distorting it: a wrong fact in the summary spreads |
| Fits | Short, tool-heavy workflows | Long threads with decisions to carry |
A rolling context window is trimming: the newest turns stay and the oldest drop out first. Anthropic notes that chat interfaces like claude.ai can manage the window this way (Anthropic). Our LangChain memory guide shows trimming and summarizing in code.
What should a summary keep?
A compression ratio only measures size. Cutting a 12,000-token conversation to 3,000 tokens is a 4:1 reduction, and that number says nothing about whether the one constraint that mattered survived. Write the summary for the next step. It should keep:
- decisions, with the reason for each
- constraints and exceptions, worded exactly
- identifiers, numbers, file paths and amounts, copied rather than paraphrased
- open questions and failed attempts
- what was proposed versus what was actually done ("draft written, not sent")
- where the evidence lives, so a later step can reopen it
Anthropic's advice for compaction prompts is to start by maximizing recall, so nothing relevant gets dropped, and then trim what's superfluous. Clearing old tool results is one of the safest, lightest forms of compaction (Anthropic, Sep 2025). If the default summary drops something your later turns need, Claude's API lets you write your own summarization prompt (Anthropic).
Test the summary like any other feature
Write down the questions the next step must answer. Ask them with the full history and with the summary, using the same model, and compare. Then compact a few times in a row: when each summary is written from the previous one, errors compound, which OpenAI's cookbook calls context poisoning (OpenAI).
Leaving something out of the prompt isn't the same as deleting it. Keep the original so retrieval can bring back the exact wording when a later step needs it.
Retrieval and memory: bring back only what the step needs
Compaction keeps one session going. Retrieval and memory decide what comes back from outside the window: a passage from a document, a decision from last week, a user's preferences. Neither raises the model's limit. They spend the window on the right tokens.
- Retrieval keeps documents and records outside the prompt and selects the passages that are relevant and allowed for this request.
- Memory saves what should outlast the session (facts, preferences, decisions) and loads the relevant part back when a new session starts. Coding agents get it from a plugin (coding agents), chat apps from an MCP server, and your own agent from a few API calls (quickstart). The context memory guide explains how the window and memory fit together.
With supermemory, one search call returns the memories and document chunks that match the current message, scoped to a single user's namespace, so the window gets a handful of relevant lines instead of the whole history (search docs). If you build on the Vercel AI SDK, the AI SDK integration injects the user's profile into every call, plus the matching memories in its full mode.
Semantic compression, step by step
Semantic compression treats a long document as a set of topics and compresses each one (Fei et al., 2023):
- Split the text into sentence-level blocks of a set length.
- Embed each block with a sentence embedding model (the paper uses all-MiniLM-L6-v2) and build a graph whose edges are the similarities between blocks.
- Cluster the graph to find groups of blocks about the same topic.
- Compress each group in parallel with a pretrained summarization model (the paper uses distilbart-cnn-12-6).
- Reassemble the compressed pieces in the original order and send them to the LLM.
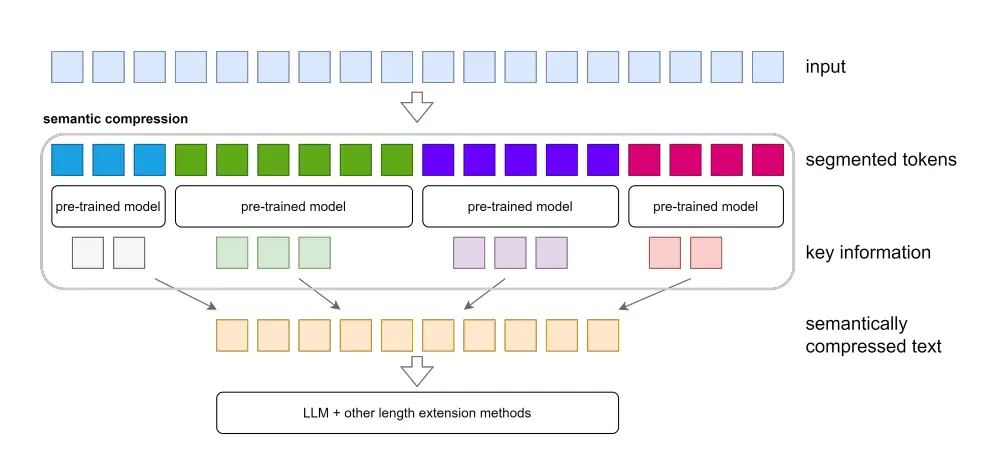
The result is roughly 6 to 8 times shorter than the input. In the paper's passkey retrieval test, Llama 2 with a 4K window dropped to zero accuracy once inputs passed its window. With compression, accuracy stayed above 90% for inputs up to 30,000 tokens, and combined with YaRN it stayed above 90% up to 60,000 tokens.
If you build it yourself, watch for these:
- The embedding model can truncate long blocks before the summarizer ever sees them.
- A cluster can exceed the summarizer's input limit even when every block fits on its own.
- Cluster labels aren't positions. Reassemble by each block's original position, or the story comes back out of order.
- Some clustering implementations expect non-negative similarities, and cosine similarity can be negative.
- Summaries can drop exceptions and turn hedged statements into facts, so test them the way the compaction section describes.
The reproduction code from the first version of this post is on GitHub. Check it against the points above before you reuse it.
Common questions
Can I increase the context window in ChatGPT or Claude?
Not directly. The window comes with the model. Chat apps keep long conversations going by managing the window for you, for example by dropping the oldest turns first, which Anthropic notes claude.ai can do (Anthropic). For details to carry between chats, you need memory, not a bigger window.
Is there an LLM with an unlimited context window?
No. Every model has a fixed limit. Products that offer endless chat keep the conversation going with the toolkit above: compacting old turns and retrieving what's relevant.
Does retrieval increase a model's context window?
No. It chooses what to send from storage outside the model. The model's limit stays the same.
Is compression lossless?
No. Summaries can omit or distort information. Test what survives against the task, and keep access to the original.
What's a rolling context window?
A window that keeps the most recent turns and drops the oldest when space runs out, first in, first out. It's cheap and predictable, and it drops older constraints abruptly once they scroll out.