Blog·Engineering

Architecting a memory engine inspired by the human brain
By Dhravya Shah·5 min read

Supermemory banner reading "Architecting A Memory Engine" with a glossy blue brain icon between the words

Language is at the heart of intelligence, but what truly powers meaningful interaction is memory — the ability to accumulate, recall, and contextualize information over time.

Large Language Models (LLMs) have mastered language, but memory remains their Achilles’ heel. Every leap in context window size is quickly outpaced by real-world demands: users upload massive documents, have lengthy conversations, and expect seamless recall of preferences and history. The result? LLMs that forget, hallucinate, and frustrate users to the point of wanting to just start over with a clean slate.

At Supermemory, the idea wasn’t always to help models remember better. It started off as a way to make *you* remember your bookmarks.
Then, it was a cost and accuracy efficient way to easily implement RAG in your product.
The more experience we had with this pain point, the more we were led to tackle context, and that’s what it currently stands as — a drop-in memory layer for your LLMs that is extremely scalable, with sub-400ms latency and enterprise-grade reliability.

Long context does not really solve this either - as found in popular papers and proven time and time again in real-world use-cases.


But why?

What Makes Memory for LLMs So Hard?

Building a memory layer for AI isn’t just about one more layer of data storage. You need to optimize for five uncompromising requirements:

  • High Recall & Precision: Always surface the right information — even across years of chat history or thousands of documents, and filtering out irrelevant, outdated, or noisy data to keep responses accurate.
  • Low Latency: Memory shouldn’t slow you down. It needs to work fast, especially at scale.

    This is particularly a challenge - because all current solutions for memory are not built for scale.
    • Vector Databases: Either get too expensive, or too slow as they grow. There are new, proprietary, server-less options now - but we'll get into this shortly
    • Graph: To add every node, or for every query, one typically has to traverse factors or magnitudes more edges than nodes.
    • Key-value: The entire KV pair has to fit inside the context length of models. Which moves the problem from one context length to another.
  • Ease of Integration: Developers need APIs and SDKs that require minimal changes to integrate — not weeks of onboarding or complex migrations.

    Managing embeddings, migrating between them, doing research for new improvements, etc. is usually not the primary business goal for apps needing memory. Lots of engineering hours are wasted.
  • Semantic & Non-Literal Queries: Memory must understand nuances, metaphors, and ambiguity — not just literal matches. Humans don’t search against a corpus of data with search terms they kinda know.

    What is "Non-literal match", here's an example
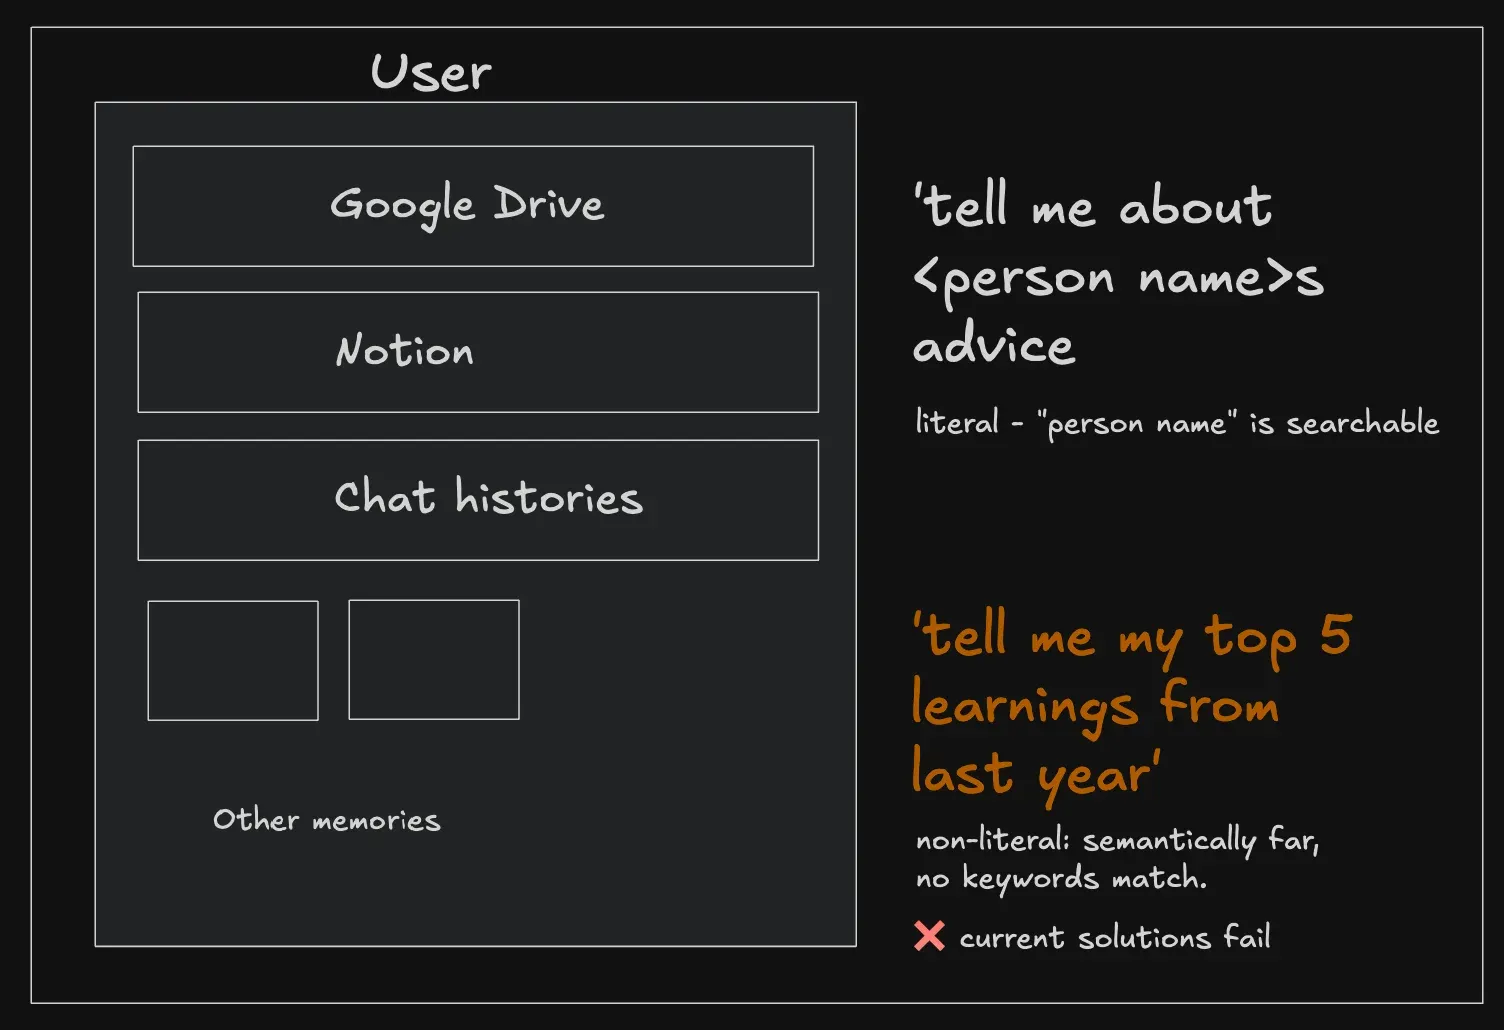
Diagram contrasting a literal searchable query against a non-literal semantic query that current memory solutions fail

Most solutions optimize for some of these, but fall short on others — especially when it comes to semantic understanding and scaling to billions of data points - For example, a user asking questions about all their internet life may ask more “general” questions that require knowledge of the entire dataset, not just ability to fuzzy search keywords.

The Supermemory Approach: Human Memory at Scale

Your brain doesn't store everything perfectly as you see it—and that's actually a feature, not a bug. It forgets the mundane, emphasizes what you've used recently, and rewrites memories based on current context. Our architecture works the same way, but engineered for AI at scale.

Smart Forgetting & Decay

Just like you naturally forget where you parked three weeks ago but remember yesterday's important meeting, our system applies intelligent decay. Less relevant information gradually fades while important, frequently-accessed content stays sharp. No more drowning in irrelevant context.

Recency & Relevance Bias

That thing you just talked about? It gets priority. That document you reference constantly? It stays top-of-mind. We mirror your brain's natural tendency to surface what's actually useful right now, not just what's technically "relevant" to a search query.

Context Rewriting & Broad Connections

Your brain doesn't just file away facts—it rewrites them based on new experiences and draws unexpected connections. Our system does the same, continuously updating summaries and finding links between seemingly unrelated information. That random insight from last month might be exactly what you need for today's problem.

Hierarchical Memory Layers

Like how you have working memory, short-term memory, and long-term storage, we use Cloudflare's infrastructure to create memory layers that match how you actually think. Hot, recent stuff stays instantly accessible (we personally use KV). Deeper memories get retrieved when you need them, not before.

Building on top of the engine

Supermemory isn’t just another vector database or RAG toolkit. It’s a universal memory layer that gives your LLMs the power of infinite context, with near-instant plug-and-play integration. Add our endpoint to your existing AI provider, plug in your API key, and boom — you’re done.

On top of this engine, we've been building some interesting products and experiences -

  • Memory as a service: Storing and querying multimodal data, at scale, with support for external connectors and sync with Google Drive, Notion, OneDrive, etc. It's a few API calls - just /add, /connect, /search docs.supermemory.ai/api-reference/manag…
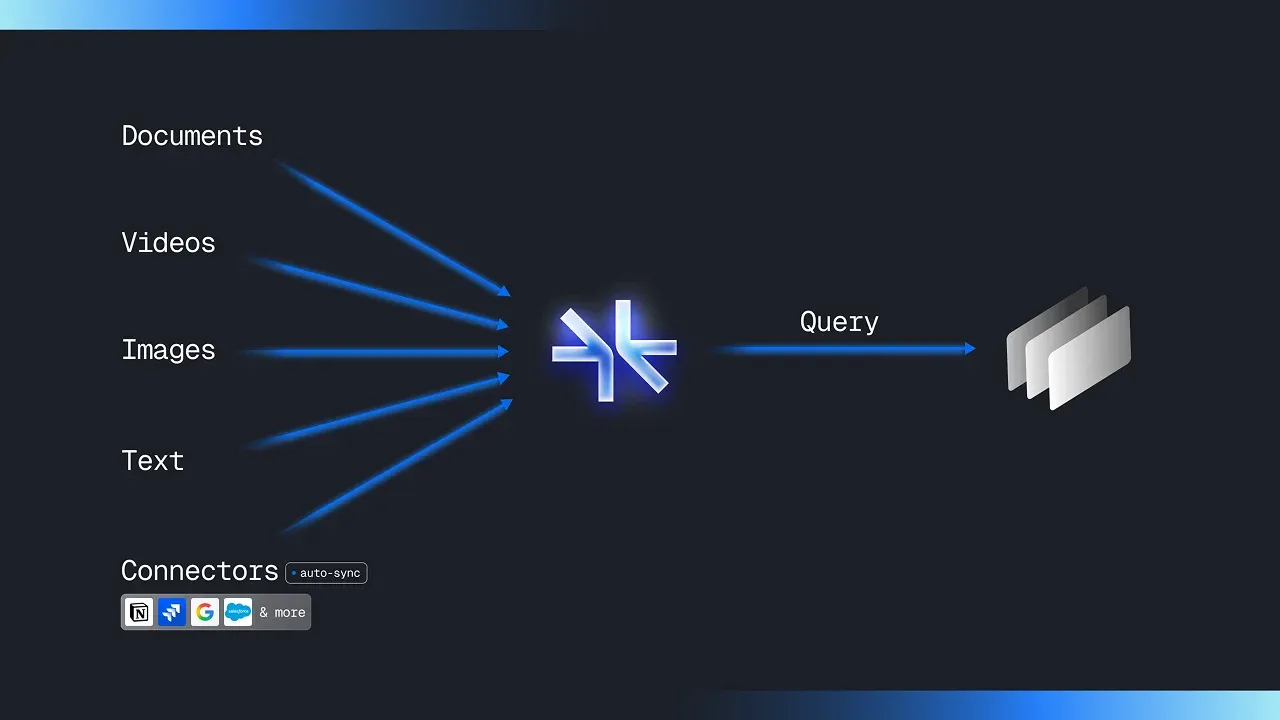
Diagram showing Documents, Videos, Images, Text, and Connectors flowing into Supermemory, then queried for results
  • The Supermemory MCP: Model-interoperable MCP server that lets users carry their memories, and chats, through LLM apps without losing context. This is actually built on top of our own Memory as a service

And our latest launch, called Infinite Chat API, manages memories inline with the conversation history to only send what's needed to the model providers. Leading to less token usage, cost savings, better latencies and better quality responses.
You heard that right. You can use it today with just one line of code!

We've been constantly improving this with our latest benchmarks, work and progress in the field.
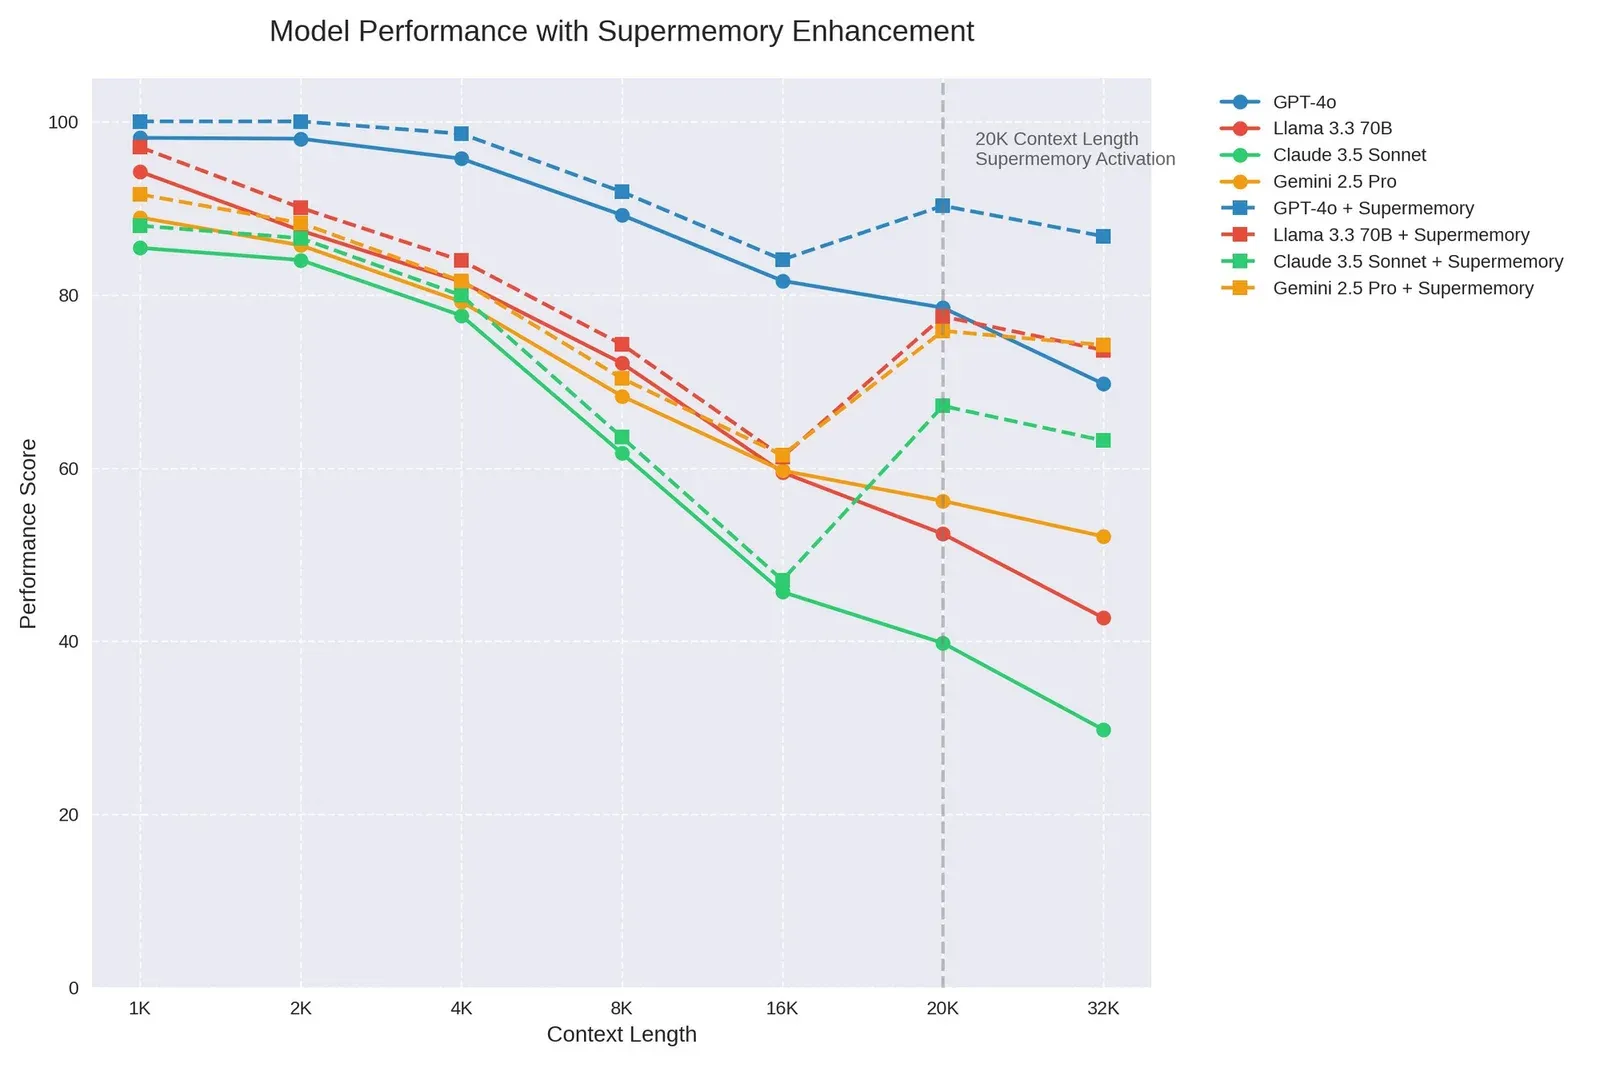
Line chart: Supermemory-enhanced GPT-4o, Llama, Claude, and Gemini score higher than baselines, especially past 20K tokens

Memory is a huge missing piece on the road to AGI. With Supermemory, you can finally build products that remember, reason, and respond like never before.

If you believe in the mission, we're hiring. If you want better memory for your LLMs and apps - you can use all these products today. Check out our docs, MCP, and get an API key on our dashboard

  1. An update to supermemoryWe've discontinued the supermemory company brain and Nova. Everyone who was charged has been refunded, our MCP and plugins continue to run, and we're going all in on the memory engine.
  2. SMFS: making agentic retrieval 55% cheaper AND more accurateWe launched SMFS.ai (Supermemory Filesystem) a few weeks ago, with a simple bet: We can redesign the filesystem specifically for agents, with special files, structures, and commands that it can use for it's tasks. Today, SMFS is used by hundreds of companies to power their agents.
  3. Introducing Dynamic Dreaming: supermemory now connects the dots, for you.Dreaming is magical. TLDR: We're launching Dynamic Dreaming in supermemory today, which automatically works if you're using supermemory in any way - API, OpenClaw, Hermes agent, etc.
  4. Dear reader, we just made supermemory insanely cheap... the Context CloudWhen I first started building supermemory, I had one goal: To build the best memory system for AI. I would talk to customers, and find out that memory was not the only thing they needed - They were all setting up 7-8 different vendors at the same time.
  5. Introducing @supermemory/tools v2.0.0Today we're releasing v2.0.0. This release unifies the API across all agents sdk integrations from AI SDK to Mastra, makes conversation identity a first-class concept, and ships with memory saving on by default.
  6. supermemory will make your Hermes-agent crazy powerfulToday, we are launching supermemory support to your Hermes agent TLDR: you can use supermemory now in your Hermes agent, it totally free to get started - https://supermemory.ai/docs/integrations/hermes In case you missed it: Hermes Agent is a self-improving AI agent from Nous Research.
  7. Solving the Precision-Recall Tradeoff: Search Result AggregationWhen you're building memory for AI, search is your foundational layer. The way search generally works is straightforward: the user defines a query, and then sets a limit (top-K) on how many search results they want returned. Usually, this is set to 10 or 20.
  8. Infinitely running stateful coding agentsWe built a plugin for Claude Code and OpenCode that gives your coding agent persistent memory. It remembers your preferences, learns your codebase, and never loses context mid-conversation. The result is an agent you can run for months without starting over.
  9. Why everyone is complaining about OpenClaw's memory (it sucks) - and why supermemory fixes it.TLDR: Today, we are releasing a new version of our openclaw plugin - https://github.com/supermemoryai/openclaw-supermemory. This post is going to be a bit technical, so bear with me (or bookmark for later!) In this post, I will talk about what we do about OpenClaw memory, and how we fix it.
  10. We added supermemory to Claude Code. It's INSANELY powerful now...Today, we are launching the Supermemory plugin for Claude Code! TLDR: You can use supermemory in claude code now. - https://github.com/supermemoryai/claude-supermemory Claude code has genuinely changed how I work. But there's this one thing that drives me crazy...
  11. Clawd / Molt bot's memory SUCKS. We gave it supermemory.I'm the founder of supermemory. Clawd/Molt bot is blowing up right now, with many, many use cases. I set it up, too, and have been using it through telegram. TLDR: just go to https://supermemory.ai/docs/integrations/clawdbot to set up supermemory for your clawd bot.
  12. Catch up with our UNFORGETTABLE Launch WeekOver the last year, one belief has guided almost everything we’ve built at Supermemory AI becomes meaningfully useful only when it remembers. Memory shouldn’t be something developers rebuild from scratch. It shouldn’t be fragile, expensive, or trapped inside a single tool.
  13. Empowering the Next Generation of Founders: Supermemory Startup ProgramIf there’s one thing we’ve learned while building Supermemory, it’s that most startups don’t fail because they didn't build features; they fail when infrastructure slows them down, or they built too slow.
  14. Building code-chunk: AST Aware Code ChunkingAt Supermemory, we're building context engineering infrastructure for AI. A huge part of that is dealing with code: ingesting repos, understanding structure, and making it searchable. The problem is that most code chunking solutions are terrible. We built code-chunk to fix this.
  15. Supermemory raises $3 million with the best memory engine for LLMsToday, I am excited to announce our first funding round to accelerate our mission of building an interoperable, scalable and reliable memory for LLMs and agents. Memory is one of the hardest challenges in AI right now.
  16. Unified Memory That Works Where You Work: Your Second Brain With SupermemoryHi everyone, I’m Dhravya, the founder of Supermemory. I want to start with a little story behind why this product means so much to me. You can also skip straight to what it is and how it works below.
  17. Supermemory just got faster on PlanetScaleWhat is Supermemory? Supermemory completes the missing part of the LLM puzzle: memory. Just as memory is crucial for human intelligence, it's essential for truly intelligent AI systems.
  18. Faster, smarter, reliable infinite chat: Supermemory IS context engineering.People are obsessed with prompts and prompt engineering. Sure, what you say is important, but what the model knows when you say it is the difference between a stateless text generator and an intelligent AI system. In short, context is the most crucial component.
  19. We solved AI API interoperabilityOne API to rule them all, One spec to find them, One library to bring them all and in the TypeScript, bind them. When we were building the the Infinite Chat API, initially, we only supported the OpenAI format. This was fine, until a lot of our customers started asking, asking for more.
  20. The UX and technicalities of awesome MCPsLast month, we launched the Supermemory MCP, mostly to test our own infrastructure and get some initial traction. It blew up. To my absolute surprise, the initial launch itself got half a million impressions (!!!). Then, we launched and got #2 on ProductHunt too.