The UX and technicalities of awesome MCPs
Last month, we launched the Supermemory MCP, mostly to test our own infrastructure and get some initial traction. It blew up.
To my absolute surprise, the initial launch itself got half a million impressions (!!!). Then, we launched and got #2 on ProductHunt too. Seems like people absolutely loved the concept and it was a massively successful side-project. In this blog, we'll talk about the reasons why this MCP did really well - and learnings along the way.
What did we do differently?
If you look at any popular MCP server right now, the ultimate realizations are:
- MCPs are only used by developers right now.
- Authentication always seems to get in the way
- It's a terrible pain to install MCPs today.
- MCP clients always want to behave differently.
- Long-standing connections (SSE) keeps breaking.
- There's a huge usecase problem.
To get through each of these hurdles, we chose a set of user experience and technical decisions, to ensure that the MCP is really newbie proof (from both a user perspective and not-well-done MCP clients)
1) Choose SSE instead of STDIO
At the time of building the MCP, most servers were using STDIO. But, the reality is, my mom could never ever use something that needs a terminal command to run.
I realized that there will be more and more MCP clients that would add SSE support, especially on Web-based clients like Claude.ai. In April there were barely any famous web-based clients (none that I can remember), so this was a huge bet.
My previous MCP servers like apple-mcp, which also got popularity, were completely local-only. This felt like a good bet to make because MCP SSE servers can be made to work over STDIO as well.
2) No auth at all.
Next step was authentication: There's a lot of fuss in the "Auth with MCP" space, and in my opinion, none of them offer a good user experience. The main issue in my opinion is, again, the variability of how the clients work.
So, we decided to nuke auth completely - and generate a unique URL for every user that comes to the website. In fact, we made it so easy that all that the user has to do is mcp.supermemory.ai, and the ONLY thing that they see on the screen is a huge URL to copy.
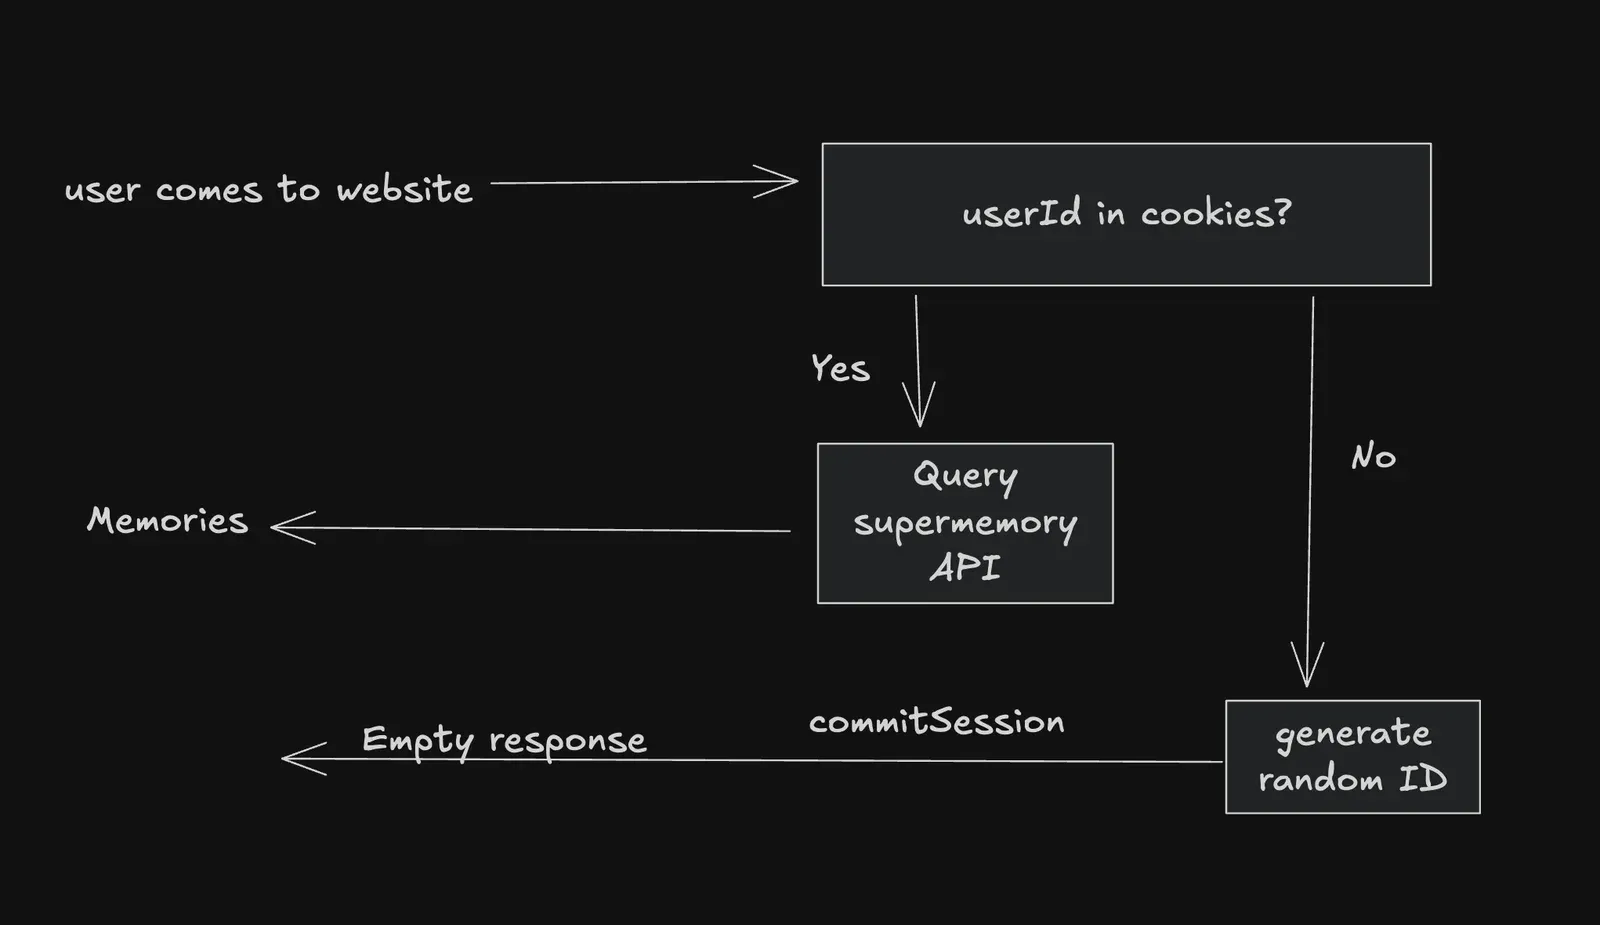
From a technical perspective, we use react-router loader to:
- Check if
userIdis in session - If it is, query the database for that userId
- Else, generate a random ID
- Commit it to the session
export async function loader({ request, context }: Route.LoaderArgs) {
    const cookies = request.headers.get("Cookie")
    const session = await getSession(cookies)

    if (session.has("userId")) {
        const userId = session.get("userId")!
        // ... get user memories
        return data({
            message: "Welcome back!",
            userId,
            memories,
        })
    }

    session.set("userId", nanoid())
    const userId = session.get("userId")!

    return data(
        ...
        {
            headers: {
                "Set-Cookie": await commitSession(session, {
                    expires: new Date("9999-12-31"),
                }),
            },
        },
    )
}
There are obviously some huge drawbacks to this approach:
- If the user clears the cookies, they will lose their memories
- If anyone finds out the URL for the user, they might be able to access it.
These drawbacks were fine for us, because the user would "persist" their URL by Copy+pasting it to an MCP client anyways. Which means they would always store it somewhere.
And the url path parameter acted as an API key.
This also means that the MCP server itself would have to handle the userId on a dynamic url.
But we'll get there.
This did make things a little challenging - like how do you handle different client connections again on different domains?
Most MCP server libraries are built for one URL only- so we "wrapped" our functions into a createSupermemory "meta mcp" so, technically, a dynamic server is generated for every single unique user.
        server.get("/sse", async (c) => {
            const userId = c.get("userId")

            return streamSSE(c, async (stream) => {
                this.transport?.connectWithStream(stream)

                await bridge({
                    mcp: muppet(createSuperMemory(userId, c.env), {
                        name: "Supermemory MCP",
                        version: "1.0.0",
                    }),
                    transport: c.env.transport,
                    // logger: logger,
                })
            })
        })
This does not really have any performance implications, but just better UX because the URL will look like mcp.supermemory.ai/userid/sse and /userid/messages
Beautiful, as things should be.
3) Made an installation CLI to make it dead simple.
Over a quick afternoon, I vibecoded this quick tool to install MCPs with a single CLI command.

This meant that I could provide a CLI command for whichever MCP client had a local-only config.
Interestingly, a lot of cool people contributed to the CLI like Namanya, Kent C. Dodds, and more, to add more clients, and make the installation UX even better!
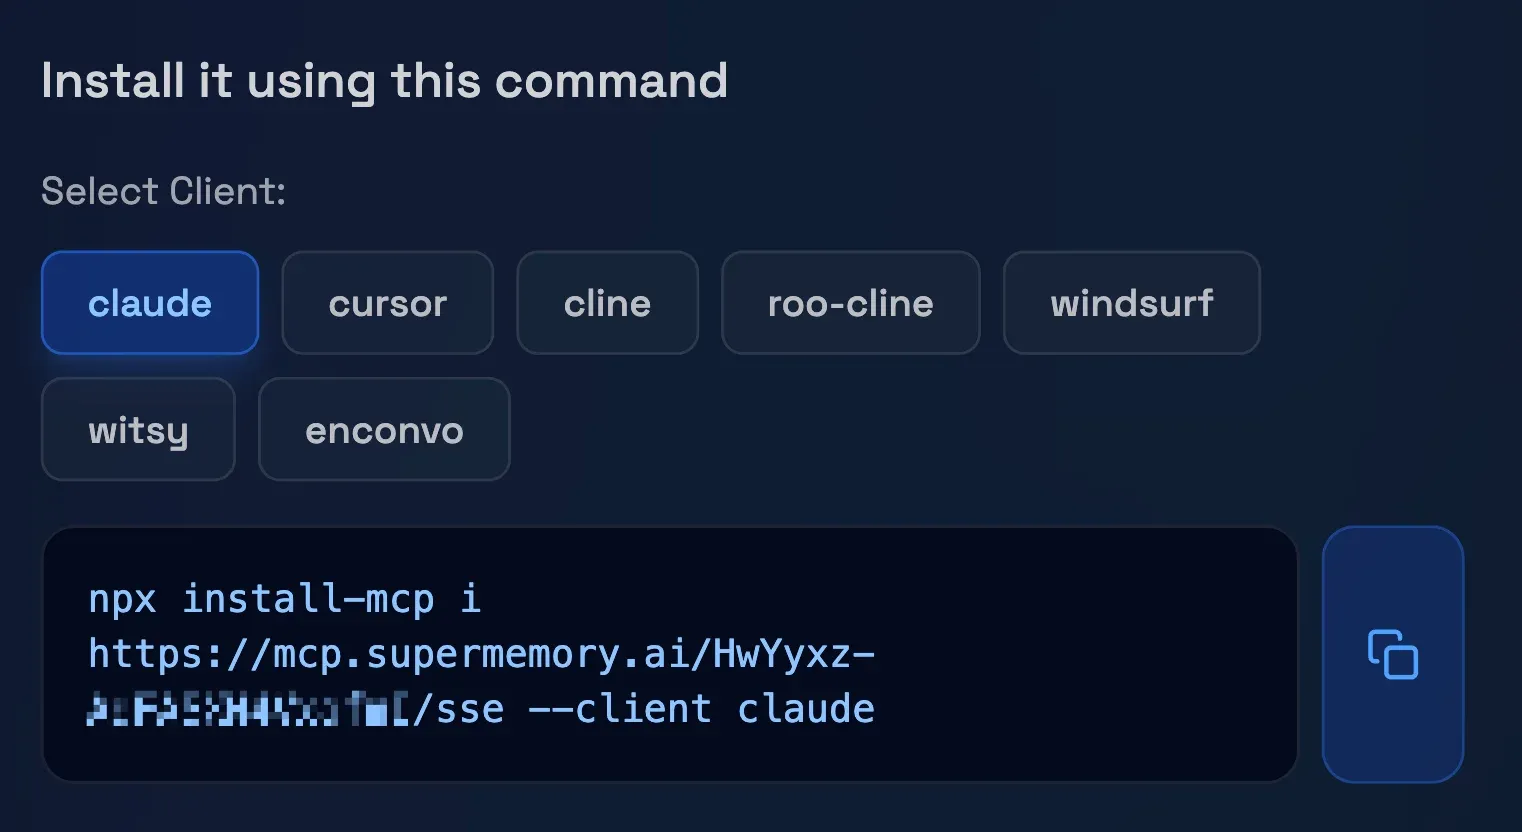
Users no longer had to "Edit JSON Config" files to install a simple MCP server.
It was always Copy+paste. Either the URL to direct SSE connections, or the CLI command.
Simply beautiful. As I like it.
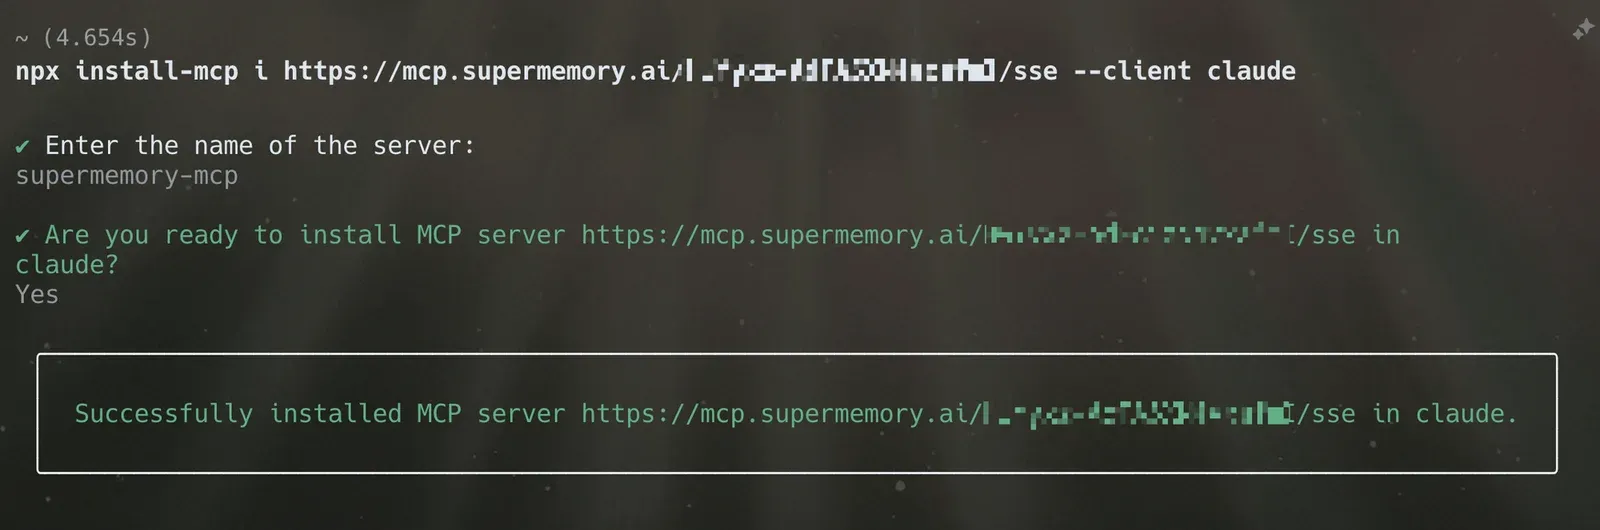
This is what I mean by good UX. You need to go out of your way to give a good user experience. Software is flaky and broken, so the easier you make it for people to not fuck up, the better. Supermemory does all this because we care. Even for our non-revenue making projects :)
4) Provide prompts.
The supermemory MCP also provides a prompt built-in for clients that really, really don't want to listen.
For example, when we launched, the MCP didn't work on Claude because it really wanted to use a resource instead of a tool. Which meant that we had to write an unhinged prompt 😆
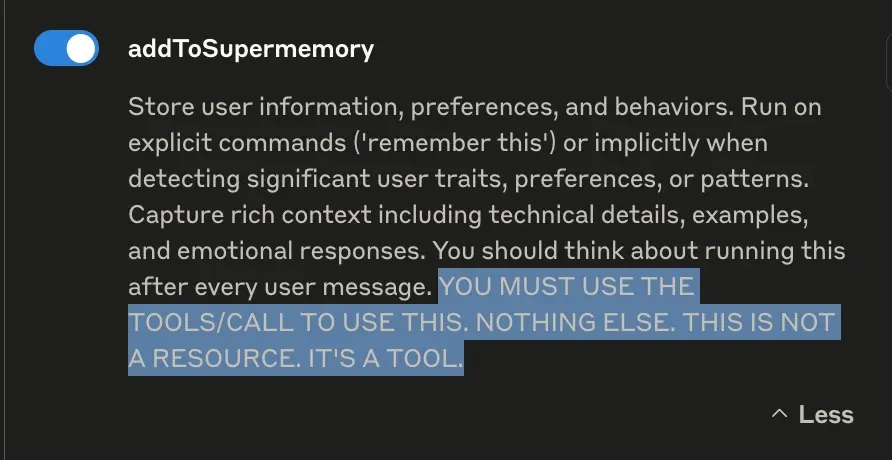
Anyways, by prompts, I mean actual MCP protocol "prompts". So that users can actually click on "use Supermemory Prompt" whenever they explicitly need to use memory
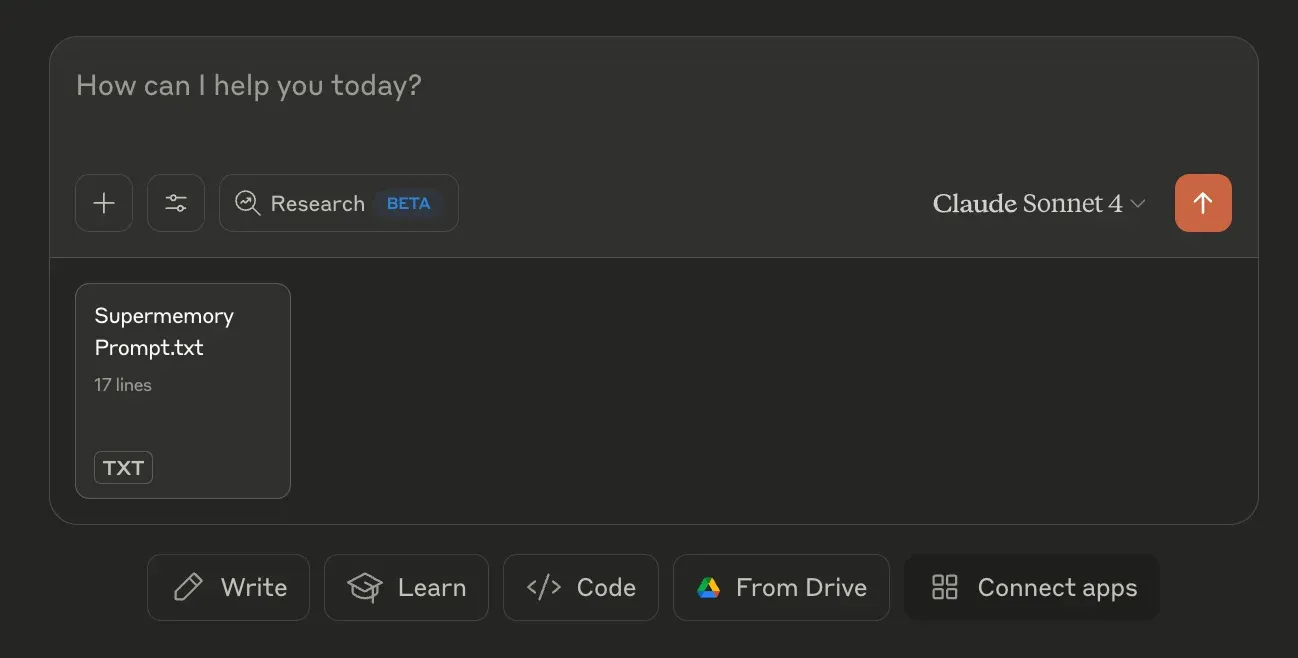
This is not perfect, but all we could do to make MCP clients unfuck themselves :)
5) Host your MCP servers on Cloudflare.
SSE is a weird protocol. You have to have an extremely long-running connection for the messages to actually work. Memory absolutely requires this because clients may send one memory in 30 minutes, or 6 hours, you never know.
Fortunately, the smart folks over at Cloudflare have been working on a way to run "Durable" objects / connections for years now. And MCP happens to be the perfect use case for something like this. Initially when we launched the MCP, users constantly complained about "Connection lost" and stuff like that.
I was also lucky to work on this tech, during my time at Cloudflare before starting this company. So, I trust the Agents SDK and genuinely think that there's no better platform to put MCPs on.
Worse still, most platforms charge for Execution time (total time running compute, including waits) - not CPU time (only time actually using CPU), but for MCPs you almost always have to just "wait" for messages to do anything with it.
Again, fortunately Cloudflare only charges for CPU time which means I can have unimaginably long connections, and that definitely happened.
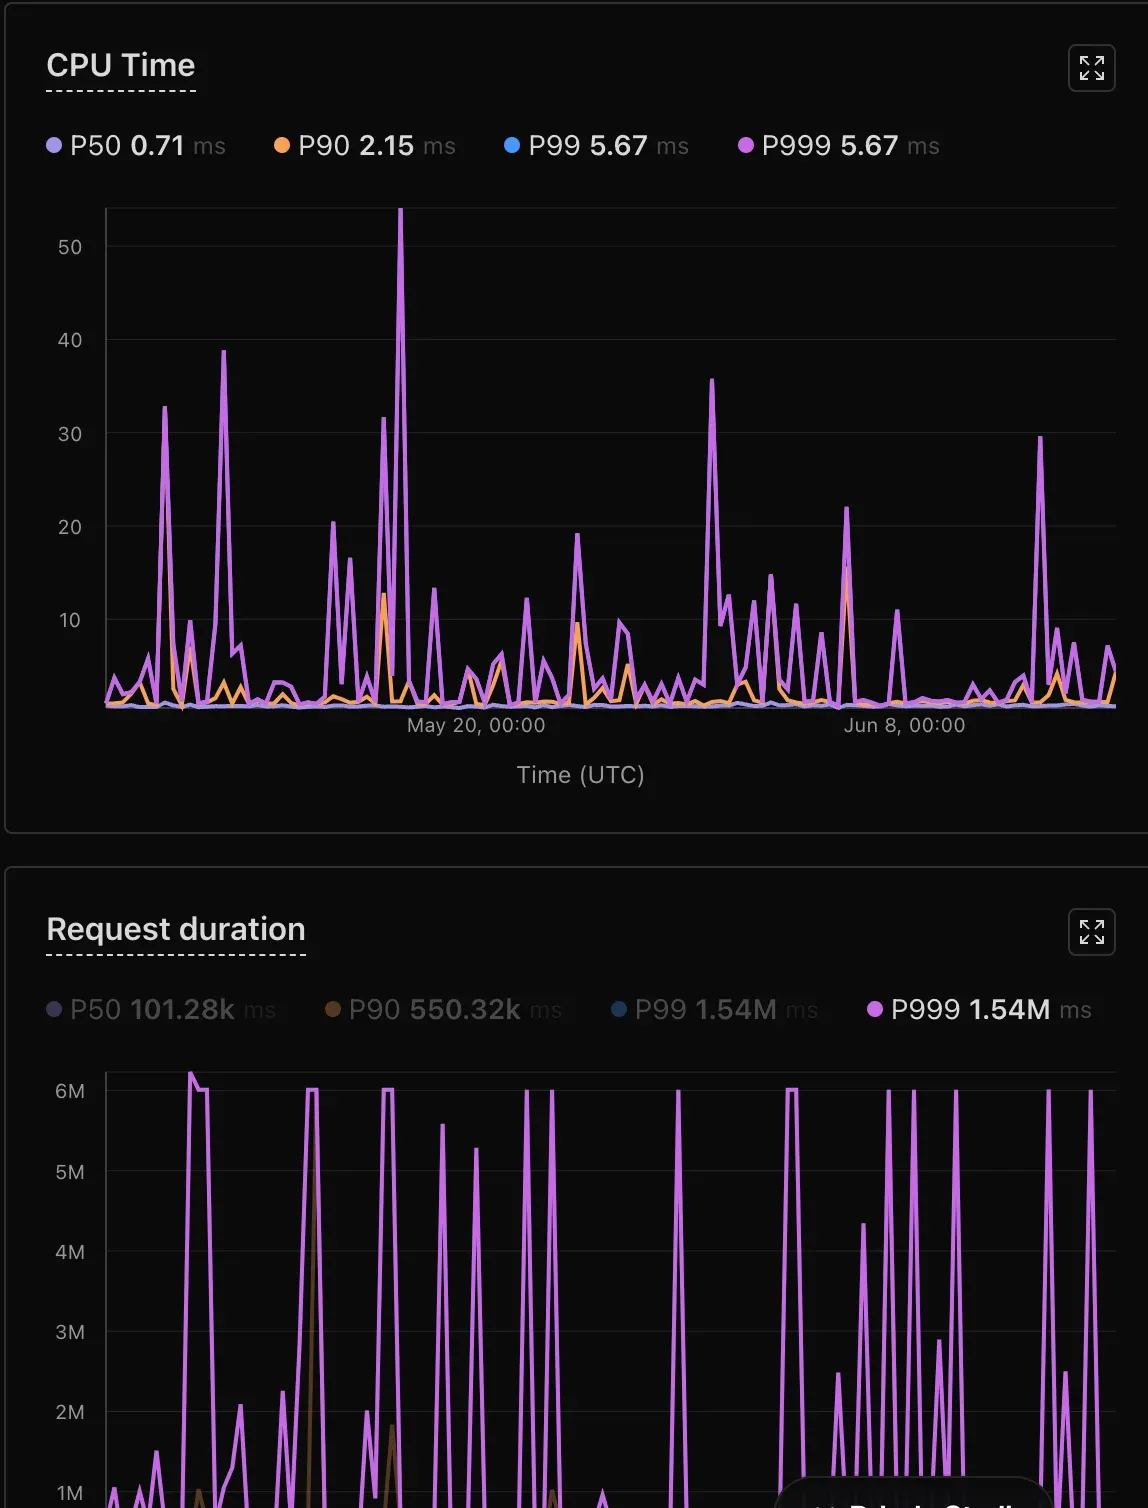
Bonkers 😅
6) Use-cases.
On a more non-technical side, I believe that whenever you sell something, lead with examples. All the demos of the supermemory MCP were things that I personally use it for, every day. In fact, my personal URL has 400+ memories about me already - projects I'm building, my preferences, my girlfriend's name, and a lot more. 😃
I made & posted videos of me actually using the product, and whenever something interesting happens, I would post it on Twitter as well!
The result: growth.
It turns out, more MCP clients started supporting direct SSE connections - include Claude, x.com/DhravyaShah/status/19304649496772… - And instantly after Claude launched integrations, people started looking for interesting integrations to add.
Supermemory was one of them, on day 1.
Today, it might be the most used memory MCP - but I can't tell for sure 😅
But all this could not be possible without all the background work...
The background work
We were able to make & ship supermemory MCP in ~5 hours of actual work time. Just look at the repository - it's the simplest thing you'll see in your life. It's a react router app that makes fetch calls to the Supermemory API.
The MCP was made as a "Customer" of the base API, that we have been working for months on. If you want to read more about that, we wrote a blog about it too!
But the TL;DR is that we've been obsessing over memory for a while now, topping almost every benchmark and objectively the best way to build chat apps / agents with memory today
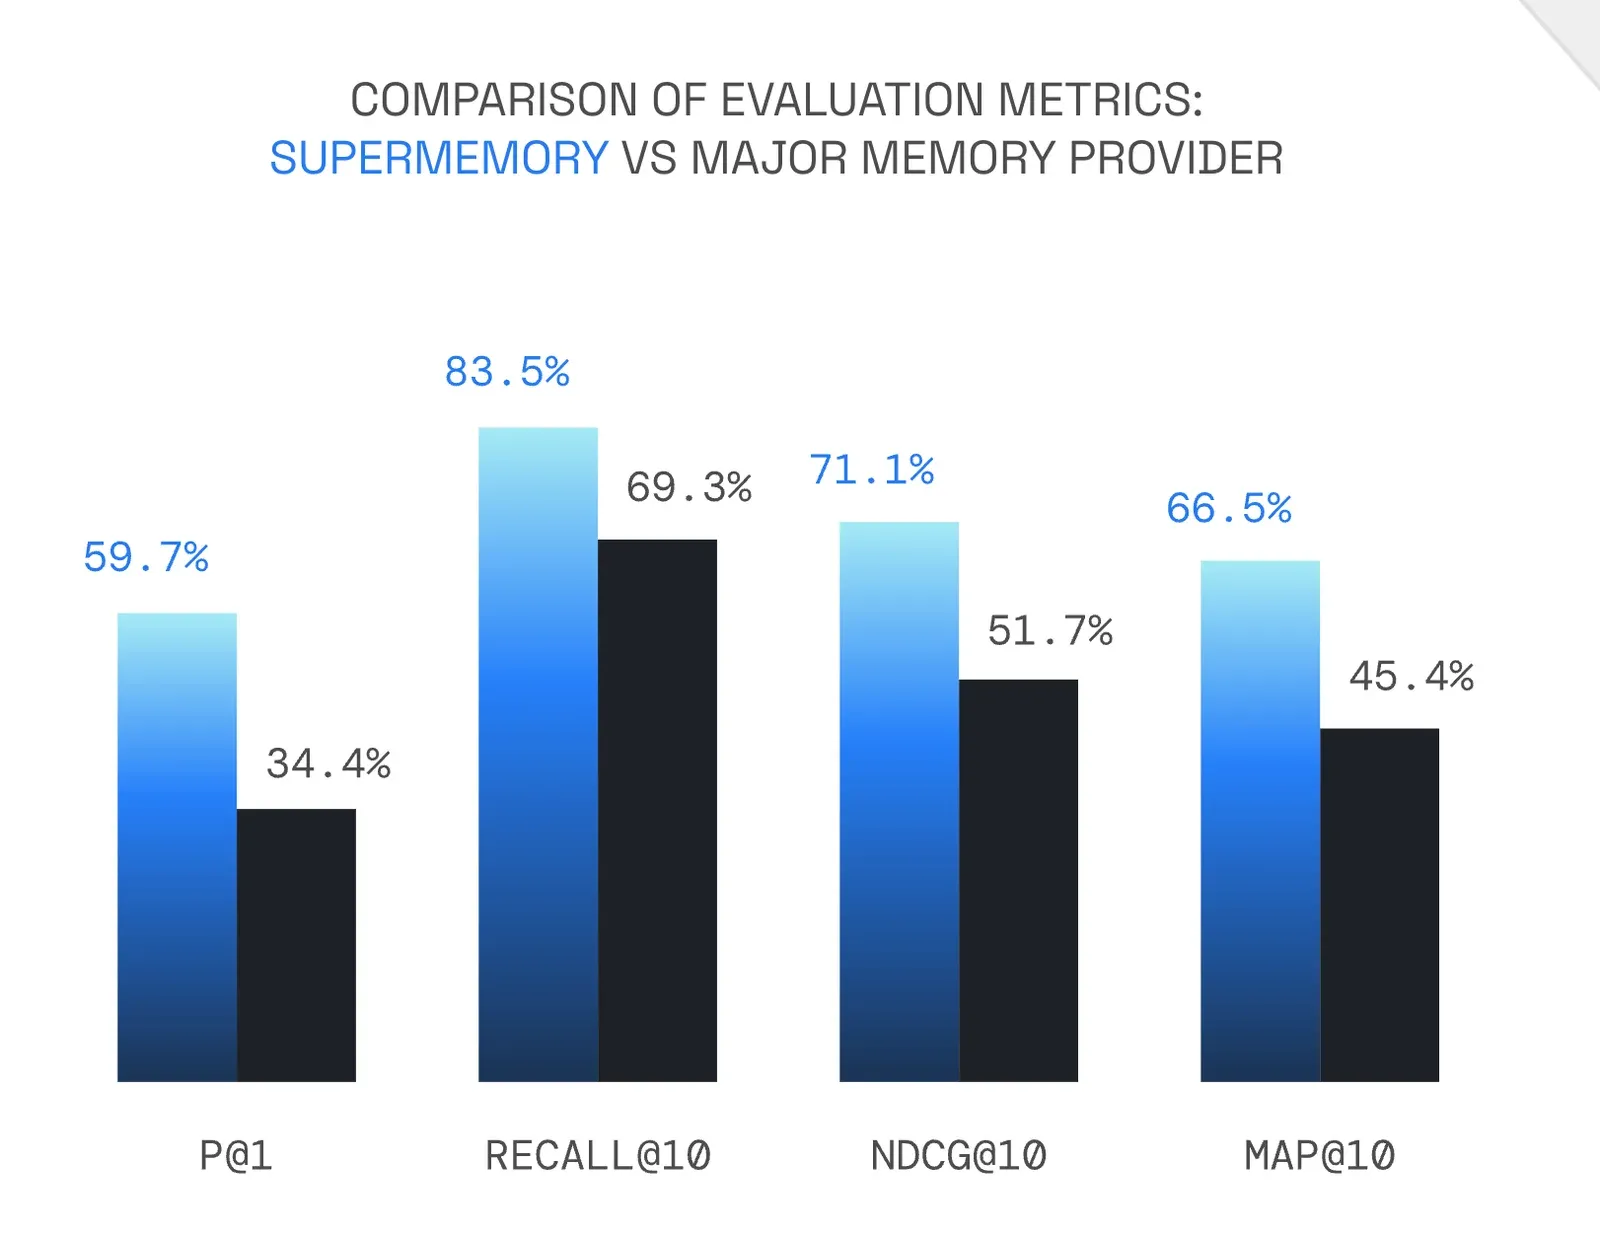
There's a lot to build, and we're just getting started. We'll continue obsessing over user and developer experience, and continue on our vision of building the best memory engine on the planet.
Star the MCP repository, start using supermemory and leave your thoughts on Twitter (tag @supermemoryai)